xianc78 @xianc78@gameliberty.club
- Sex
- Male
- Primary OS
- Linux Mint
- Programming Languages
- C/++/#, Python, Java, JavaScript, PHP, SQL, Assembly
- Ioncom Official Site
- http://ioncom.helioho.st/
Joined Jun 2020
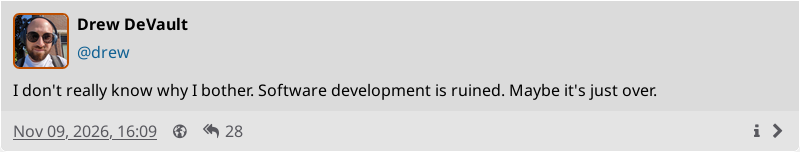
Yeah, and it's totally 100% the AI bros fault. We extremely closed minded, narcissistic, highly opinionated software devs who will intentionally break functionality in software over petty drama have absolutely nothing to do with the decline of software development and haven't at all destroy any appeal of code bases having 100% (or at least mostly) human generated code or software that doesn't include AI integration whatsoever.
xianc78
boosted

IT’S LIVE!
I finally got myself a dedicated self-hosted blog.
Which I should have done years ago. But now I’ve done it today. And frankly, this is a relief.
I miss fba.ryona.agency. It was really fun to see the stupid reasons why some people block certain instances.
xianc78
boosted

@sendpaws a lot of people who "work" on these kinds of projects dont want to complete it, in fact completing it is antethetical to their goals
They just want to have power over people no matter how miniscule like the elementary school designated as hall monitor
They just want to have power over people no matter how miniscule like the elementary school designated as hall monitor
xianc78
boosted

>stop at stop light
>see homeless guy in wheelchair asking for money
>his shift must be over, because he stands up, walks away, and another homeless guy sits in the chair and shows the same cardboard sign
>see homeless guy in wheelchair asking for money
>his shift must be over, because he stands up, walks away, and another homeless guy sits in the chair and shows the same cardboard sign
xianc78
boosted
The Conspiracy Against True Theories: Making you believe that just because it's a conspiracy, it must be false.
xianc78
boosted
_All plant-based meat alternatives and beverages are contaminated with toxins, a UK study finds_
Plants defend themselves from herbivores with self-generated toxins. Then farmers add pesticides. Then franken-meat and synth-beverage producers make things even worse.
https://expose-news.com/2026/11/10/all-plant-based-meat-alternatives-are-toxic/
Plants defend themselves from herbivores with self-generated toxins. Then farmers add pesticides. Then franken-meat and synth-beverage producers make things even worse.
https://expose-news.com/2026/11/10/all-plant-based-meat-alternatives-are-toxic/
xianc78
boosted
xianc78
boosted

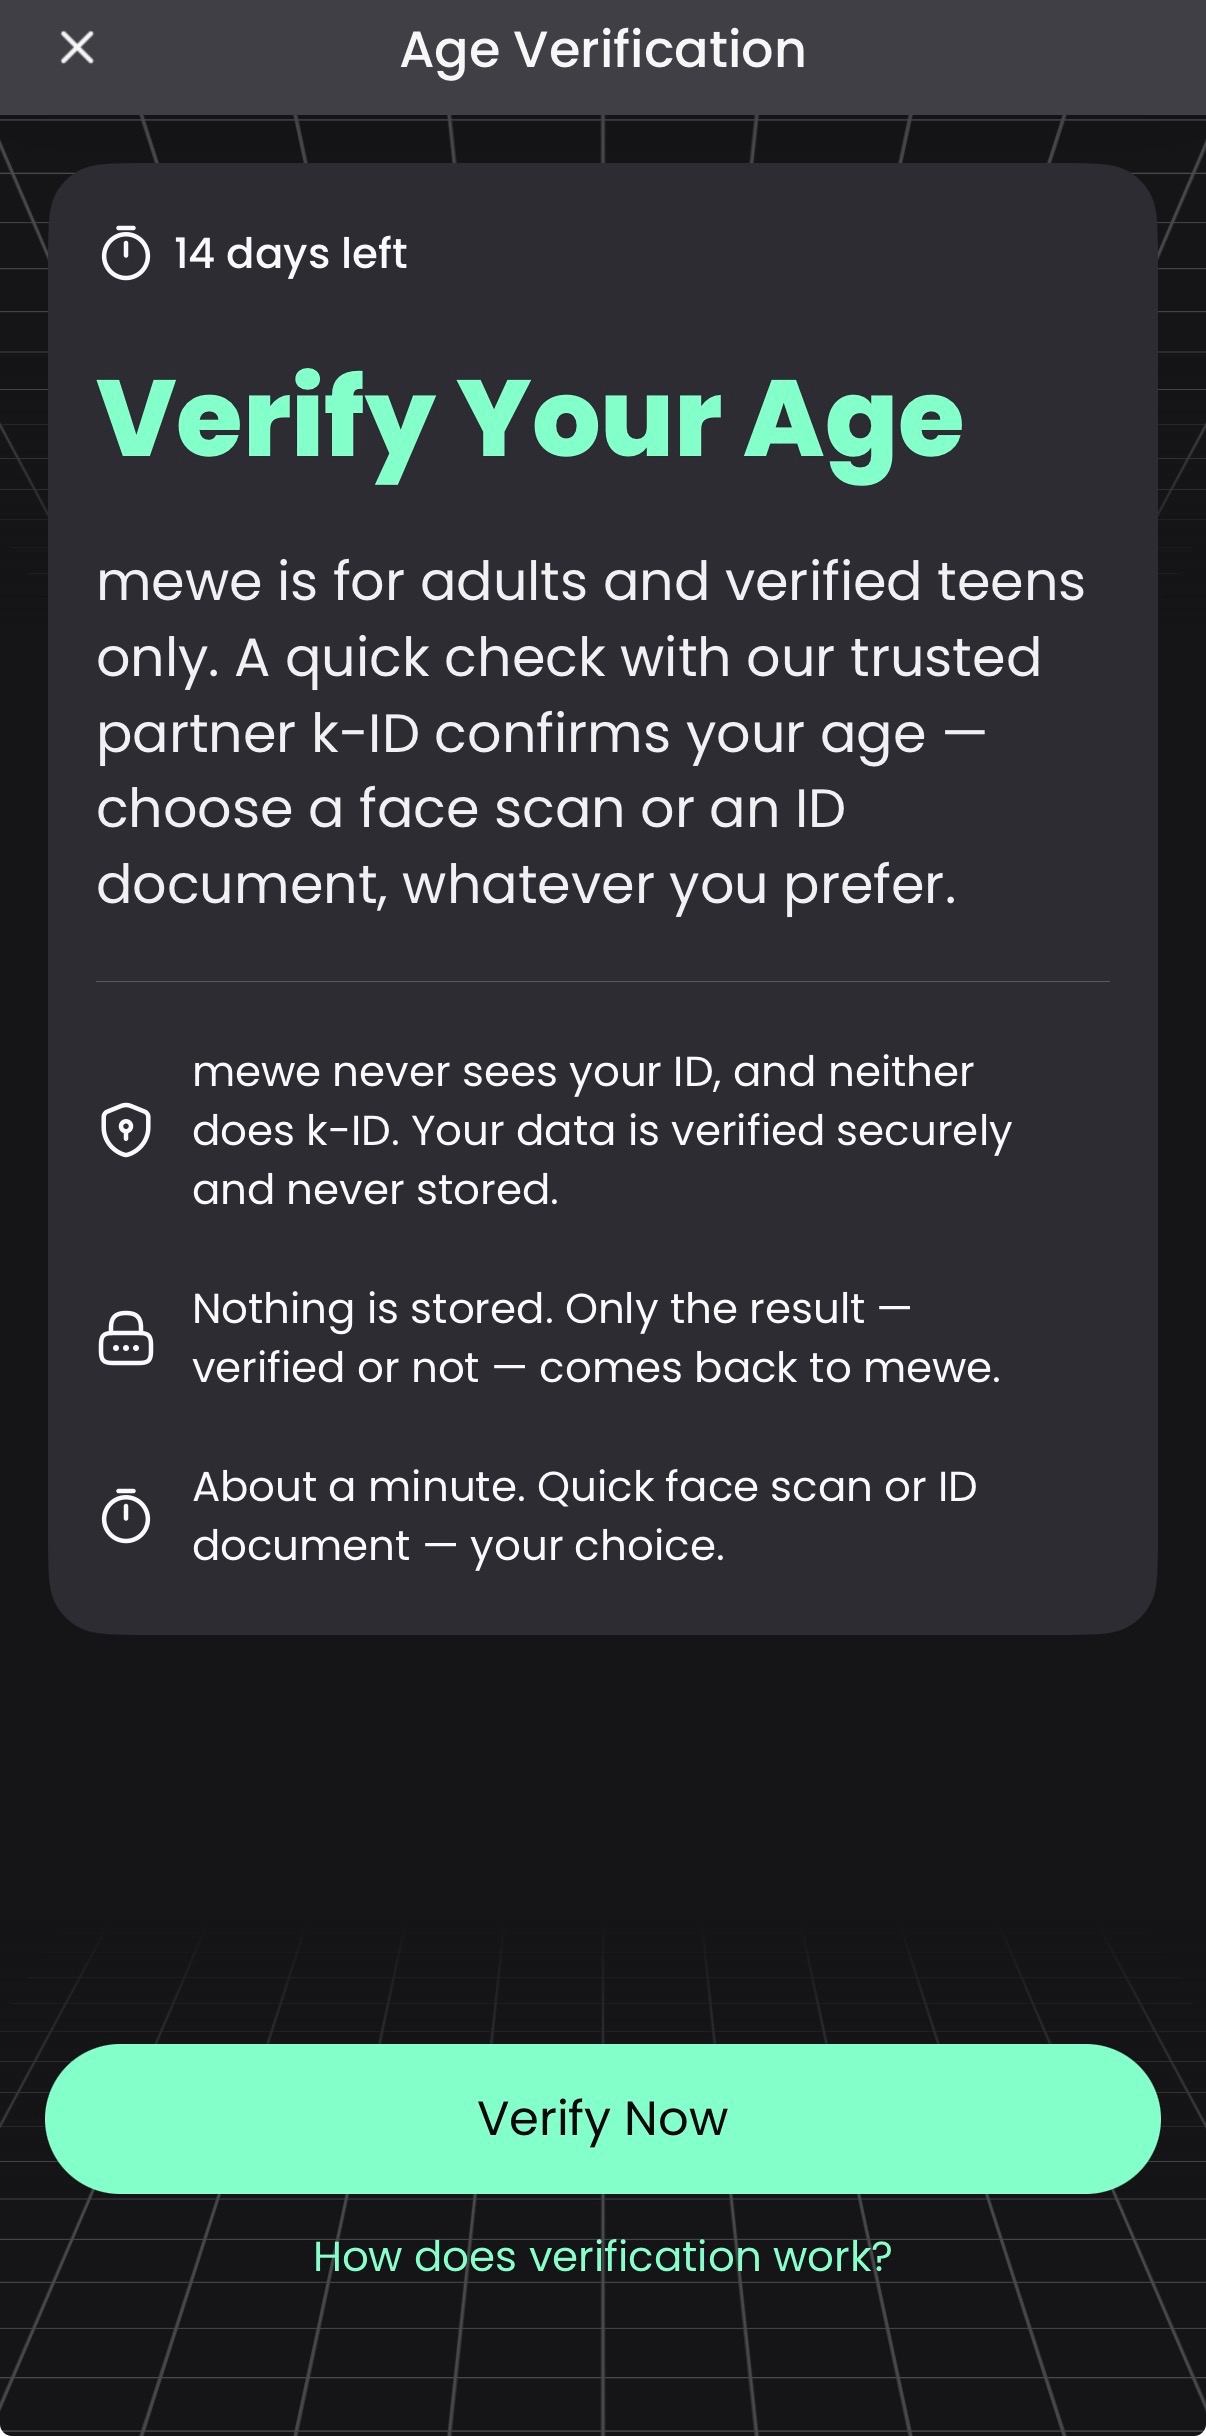
Looks like I’ll be losing my MeWe account soon. I abandoned it years ago when I had to trim down my alt-tech social media usage but checked it now and then to see how it’s developed over the years. But this pretty much seals the deal for me. 🤷♂️
xianc78
boosted
xianc78
boosted

Rust is a red flag. It implies one of two things:
1. You vibecoded your app entirely and did not review anything
Or
2. You're one of those pre-AI Rust loving freaks
1. You vibecoded your app entirely and did not review anything
Or
2. You're one of those pre-AI Rust loving freaks
xianc78
boosted
「ChatGPT has now a big problem.
Researchers at Oxford exposed a massive threat to large language models.”
It’s called "Model Collapse."
And it explains why the internet is about to become a toxic waste dump for Large Language Models.
Right now, AI companies are scraping the entire web to train their next-generation models.
But there’s a massive problem.
The internet is no longer just human data. It is rapidly filling up with AI-generated text, images, and code.
What happens when an AI trains on data generated by another AI?
A new paper in Nature just gave us the answer. And it is terrifying.
When AI models are recursively trained on AI-generated data, they suffer from irreversible brain damage.
The researchers found that the model starts forgetting the "tails" of the original data distribution. The rare, weird, unique, and complex human nuances completely disappear.
It's like making a photocopy of a photocopy.
Every generation loses resolution. The output gets flatter, blander, and more generic, until the model completely collapses in on itself.
For years, we thought the biggest bottleneck for AI was compute, getting enough H100 GPUs from Nvidia.
This paper proves the real bottleneck is us.
If we keep flooding the internet with synthetic AI slop, we will poison the very data pool required to build smarter models.
The ultimate irony? We thought AI was going to make human creators obsolete.
Instead, this research proves that verified, genuine human data is about to become the most valuable commodity in the tech industry.」
x.com/CrazyShyyt/status/2118178862823874924
「だからいったじゃーん、のお気持ち。
まあ止めようと思って止められる流れではなかっただろうが…」
x.com/tukimi_negitoro/status/2118330380382253238
xianc78
boosted
@lain@lain.com Another episode in the GNU cancel campaign using out of context quotations from a mailing list.
Someone asked a hypothetical "Would you accept a contribution if it was made using slave labour?" and the maintainer said "Yes".
That doesn't mean they endorse slavery, which is how a lot of people misunderstand it. It just means they don't care who wrote the code as long as it is free software, which is quite reasonable.
xianc78
boosted
@SuperDicq
Not only ethics is a personal choice of project leaders, they are just unenforceable. Nice to have but can understand if their interpretation of ethics really just ends at four freedoms.
I've been at both sides, and honestly it has always been a question of who you approve to use your project (but you again can't enforce that). And also having shit from both sides, none of it could be described as "cruelty free".
Not only ethics is a personal choice of project leaders, they are just unenforceable. Nice to have but can understand if their interpretation of ethics really just ends at four freedoms.
I've been at both sides, and honestly it has always been a question of who you approve to use your project (but you again can't enforce that). And also having shit from both sides, none of it could be described as "cruelty free".
xianc78
boosted
@josemanuel @SuperDicq freedom 0 haters on my timeline
xianc78
boosted
reminds me of meme licenses like Anti-Capitalist Software License or those ones forbidding governments, militaries, nuclear power plants, or russian nationals from their software.
CC: @SuperDicq@minidisc.tokyo @josemanuel@social.sdfeu.org
CC: @SuperDicq@minidisc.tokyo @josemanuel@social.sdfeu.org
xianc78
boosted
Also if you're one of those people who post that one screenshot that only includes the "Our answer must be YES." out of context without Eliz' actual reasoning included then you are an extremely disingenuous person.
xianc78
boosted
I see Eliz' post on the emacs-devel mailing list is going viral on Fedi. context
I just want to say that people who criticize this post fundamentally misunderstand the free software movement.
In my eyes I see that a lot of newgens see "free software" more as an "ethical consumption" label like "fairtrade", "organic", "cruelty free", etc. That's not what this movement is.
The free software movement sees source code as research. And good researchers do not ignore facts even if they were found by unethical experiments. They only care about getting the facts.
xianc78
boosted
@aeva@mastodon.gamedev.place Your long time criticism of the free software movement is... that it doesn't solve every problem with humanity ever but instead narrows down its scope to stay in its own lane? Huh?



- Sex
- Male
- Primary OS
- Linux Mint
- Programming Languages
- C/++/#, Python, Java, JavaScript, PHP, SQL, Assembly
- Ioncom Official Site
- http://ioncom.helioho.st/
Joined Jun 2020